Self-hosted Inference with llm-d
Federal Frontier serves open-weight models on your own GPUs through an Istio Gateway and llm-d, with multi-model routing, prefix-cache-aware and load-aware scheduling, and signed model admission in Compass.
Federal Frontier runs open-weight models on GPUs you control and puts them behind the same Compass router as your managed models. Requests go through an Istio Gateway to llm-d. llm-d picks the right model pool for each request and the best replica inside that pool. Compass admits a self-hosted model only after it checks the model’s signed bill of materials.
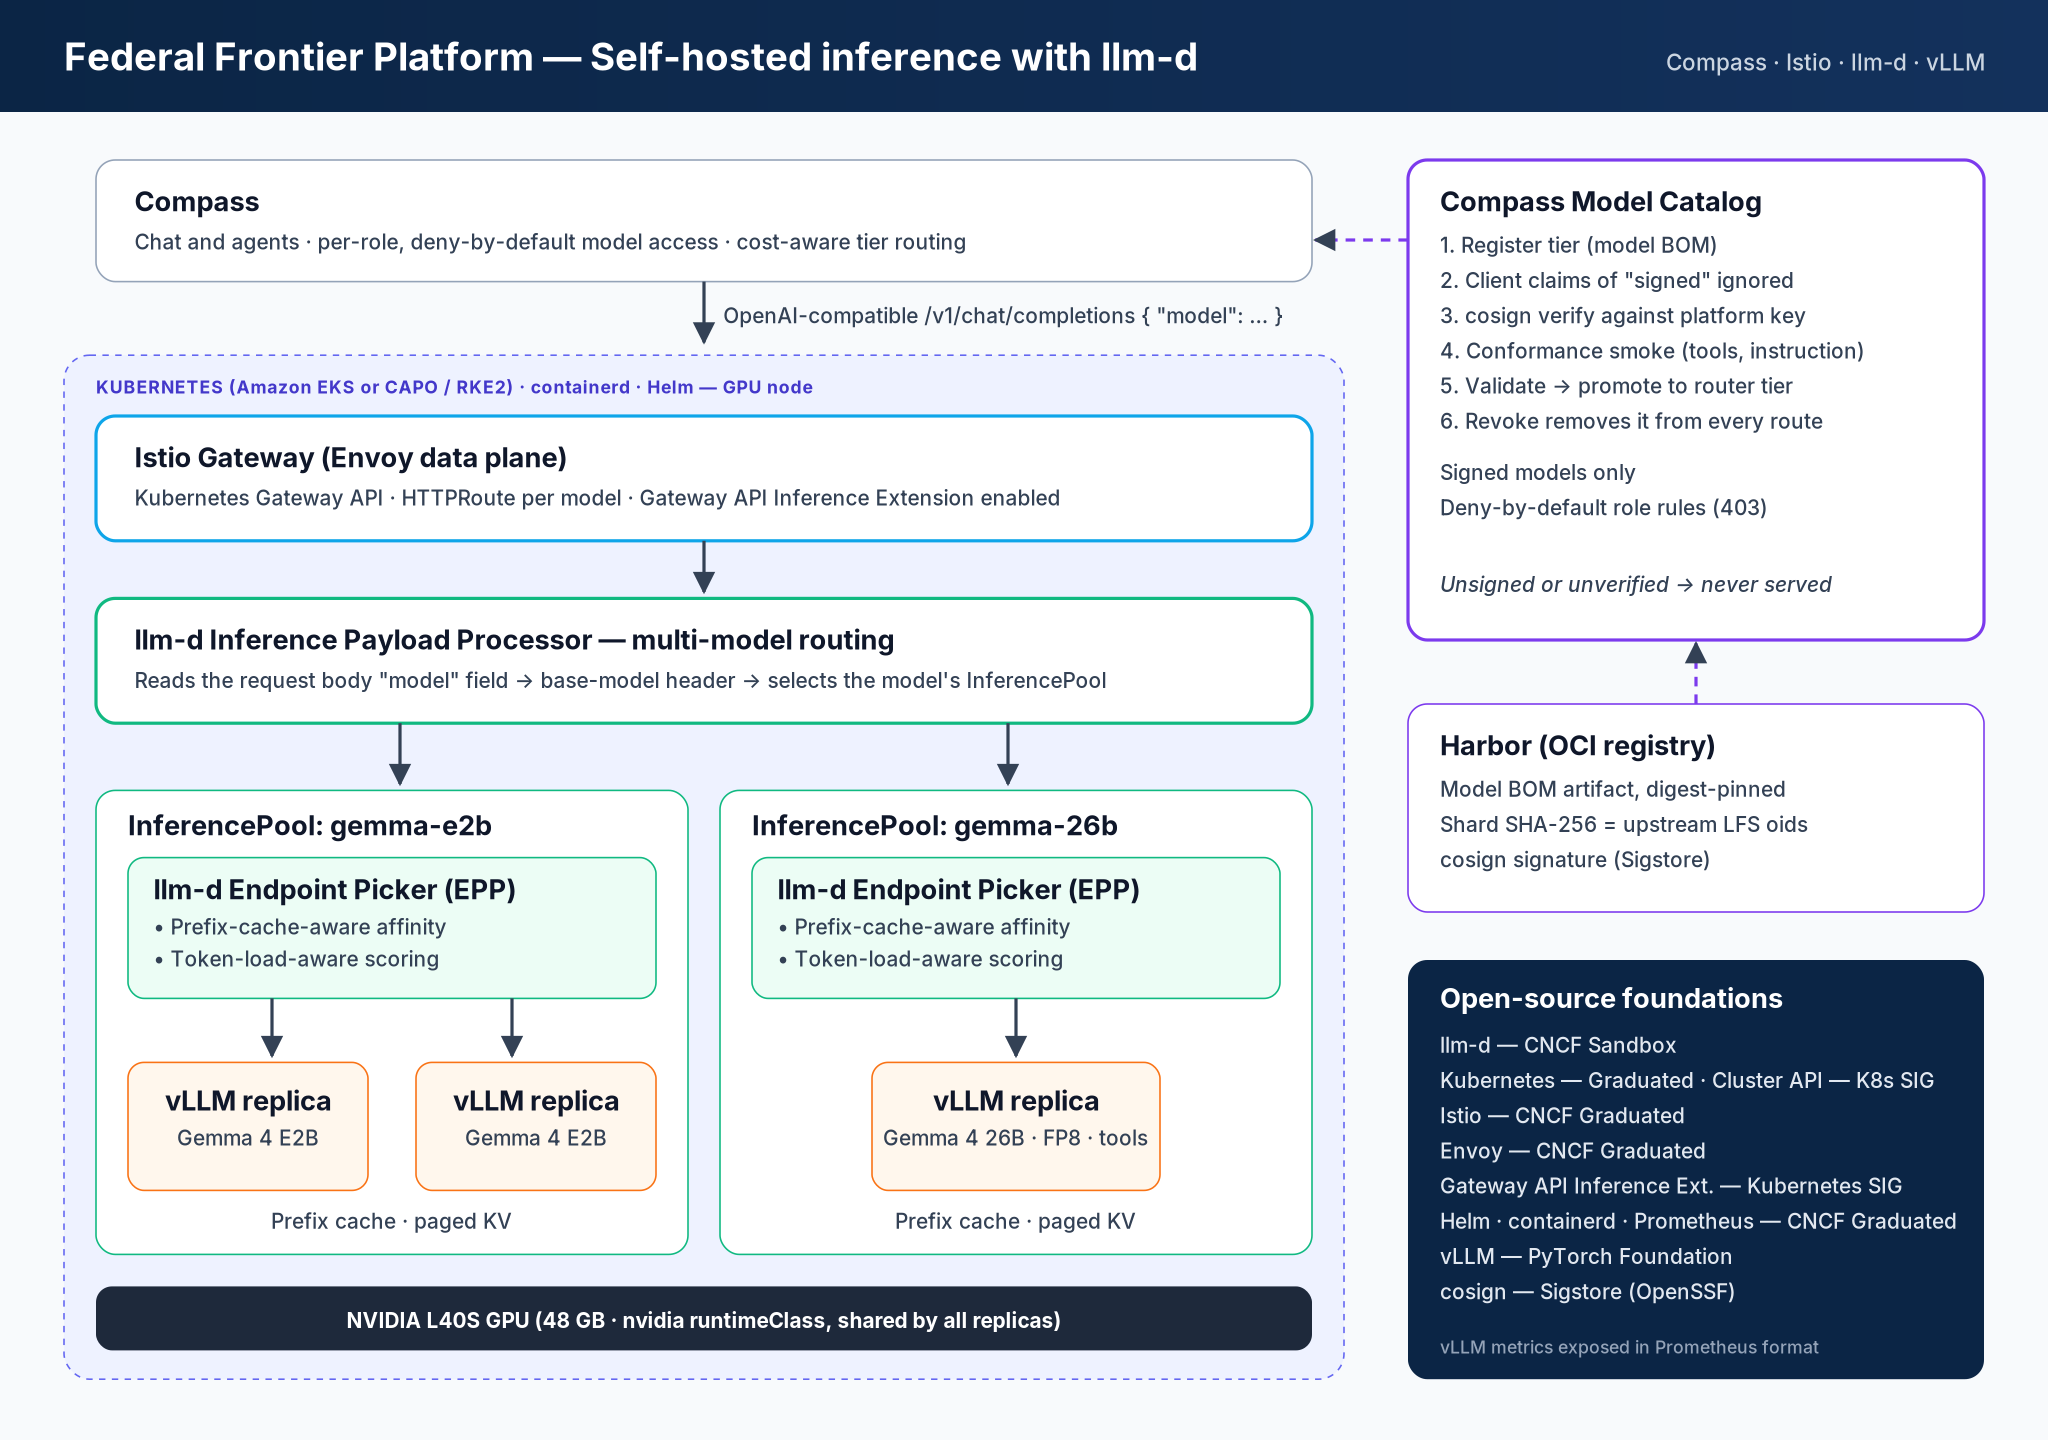
How a request flows
- Compass sends an OpenAI-compatible
/v1/chat/completionsrequest. Themodelfield names the model. - The Istio Gateway (Envoy data plane) receives the request. It is configured with the Kubernetes Gateway API and the Gateway API Inference Extension.
- The llm-d Inference Payload Processor reads the
modelfield from the request body and turns it into a routing header. The gateway’sHTTPRoutethen sends the request to that model’s InferencePool. One gateway serves several models. - Inside the pool, the llm-d Endpoint Picker (EPP) chooses a vLLM replica:
- Prefix-cache-aware affinity: requests that share a prompt prefix go to the replica that already holds that prefix in its KV cache, so the shared text is not recomputed.
- Token-load-aware scoring: concurrent work is spread across replicas based on the load each one is carrying.
- vLLM serves the model on the GPU and exposes metrics in Prometheus format.
Model admission in Compass
A self-hosted model answers Compass users only after it passes the model catalog:
| Step | What Compass enforces |
|---|---|
| Register | The catalog entry records the model’s base model, license, source commit and per-shard SHA-256 hashes. |
| Signature | The model’s bill of materials is a digest-pinned OCI artifact in Harbor, signed with the platform’s cosign key. A client cannot mark an entry as signed: that field is set only by the server’s own cosign verify. |
| Validate | Validation is refused until the signature verifies and a conformance check (tool call, answer from the tool result, exact instruction following) passes. |
| Promote | A validated entry becomes a router tier. Model access is deny-by-default: a user whose roles have no model rule gets HTTP 403. |
| Revoke | Revoking removes the tier from the route, the permitted set, any pin and every role rule. |
Measured results
These results come from a single-node deployment on one NVIDIA L40S (48 GB). It ran Gemma 4 E2B (two replicas) and Gemma 4 26B-A4B (FP8, one replica).
| # | Capability | Result |
|---|---|---|
| 1 | InferencePools for both models attached to the Istio Gateway | Both pools Accepted and ResolvedRefs |
| 2 | Prefix-cache-aware scheduling | 12 of 12 requests sharing a ~1,500-token prefix were routed to the same replica, and 89.7% of their prompt tokens were served from the prefix cache (10,560 of 11,775) |
| 3 | Load-aware scheduling | 8 concurrent long generations split 4 and 4 across two replicas |
| 4 | Multi-model routing on one gateway | 12 of 12 requests answered by the model named in the request (6 per model, confirmed by each replica’s own request counters). An unknown model returns HTTP 404 |
| 5 | Signed model admission | Client-asserted signature ignored. Validation refused before verification. cosign verify passed. Validate and promote succeeded. Conformance 3 of 3 |
| 6 | Compass chat on the self-hosted tier | A Compass chat turn was served by Gemma 4 26B through llm-d in 4.7 s at $0 model cost (1,883 prompt and 58 completion tokens). A caller with no model rule received HTTP 403 |
| 7 | Revocation | After revoke, the tier was disabled and absent from the route, the permitted set and the pin |
Components
| Component | Role | Project |
|---|---|---|
| Kubernetes (Amazon EKS, or RKE2 provisioned by Cluster API Provider OpenStack) | Cluster and GPU scheduling | Kubernetes: CNCF Graduated. Cluster API: Kubernetes SIG project |
| containerd | Container runtime | CNCF Graduated |
| Helm | Installs the llm-d router and payload processor | CNCF Graduated |
| Istio 1.29 | Gateway API implementation | CNCF Graduated |
| Envoy | Gateway data plane | CNCF Graduated |
| Gateway API Inference Extension | InferencePool API |
Kubernetes SIG Network |
| llm-d v0.11 (router, EPP) and payload processor v0.1 | Multi-model routing and inference-aware scheduling | CNCF Sandbox |
| vLLM v0.30 | Model server | PyTorch Foundation |
| Prometheus format | vLLM and EPP metrics | CNCF Graduated |
| cosign | Model artifact signing and verification | Sigstore (OpenSSF) |
| Harbor | OCI registry for model bills of materials | CNCF Graduated |